Streaming AI Workflows in Python: Kafka Queues and Flink-Powered LLM Inference
Disclaimer: The views and opinions expressed in this presentation are solely my own and do not necessarily reflect the views or opinions of my current or past employers. This presentation is based on my personal experiences and should not be interpreted as official statements or endorsements from any organization.
Agenda
Yesterday: Batch analytics told you what happened yesterday.
Today: Real-time ML inference tells you what's happening now.
Tomorrow: Real-time ML + Gen AI systems understand what's happening, explain why, and act autonomously—moving from dashboards to agents.
Real-Time Inferencing: Why It Matters
Real-Time Inferencing: Why It Matters
Any domain where the cost of being late
is higher than
the cost of being slightly wrong needs real‑time ML.
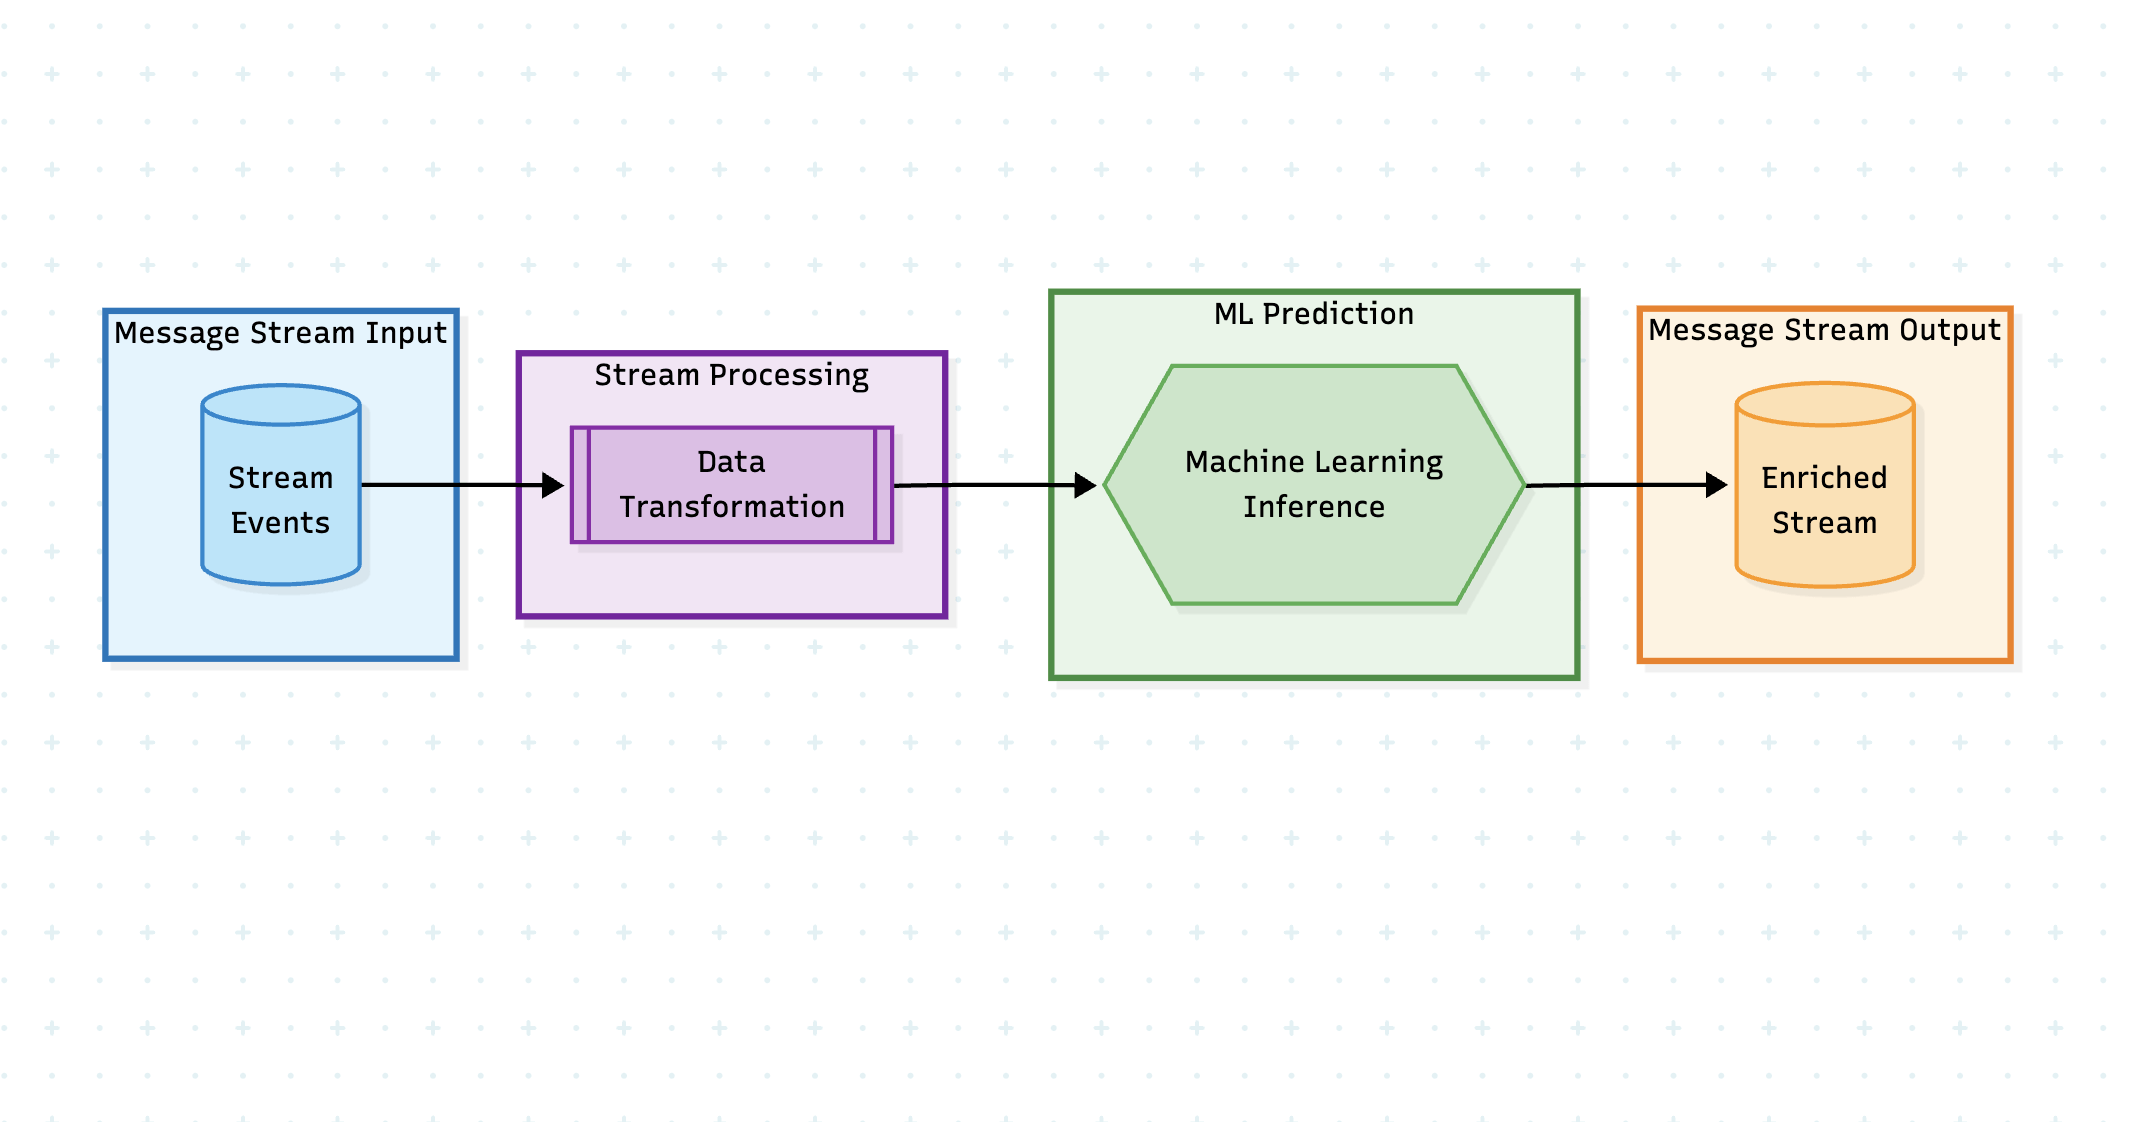
Real-Time Inferencing: Why It Matters
Native Flink AI Functions
-- CREATE MODEL: Register directly in Flink
CREATE MODEL fraud_detector
INPUT (transaction_amount DOUBLE, merchant_category STRING)
OUTPUT (fraud_probability DOUBLE)
WITH (
  'provider' = 'onnx',
  'model-path' = 's3://models/fraud_v3.onnx'
);

-- ML_PREDICT: Inline inference, zero network hop
SELECT
  transaction_id,
  ML_PREDICT(fraud_detector, transaction_amount, merchant_category).fraud_probability
FROM transactions
WHERE ML_PREDICT(...).fraud_probability > 0.85;
Flink for Real-Time Data Processing + ML API
Benefits
Drawbacks
What is getting built in Open Source ?
Flink Agent
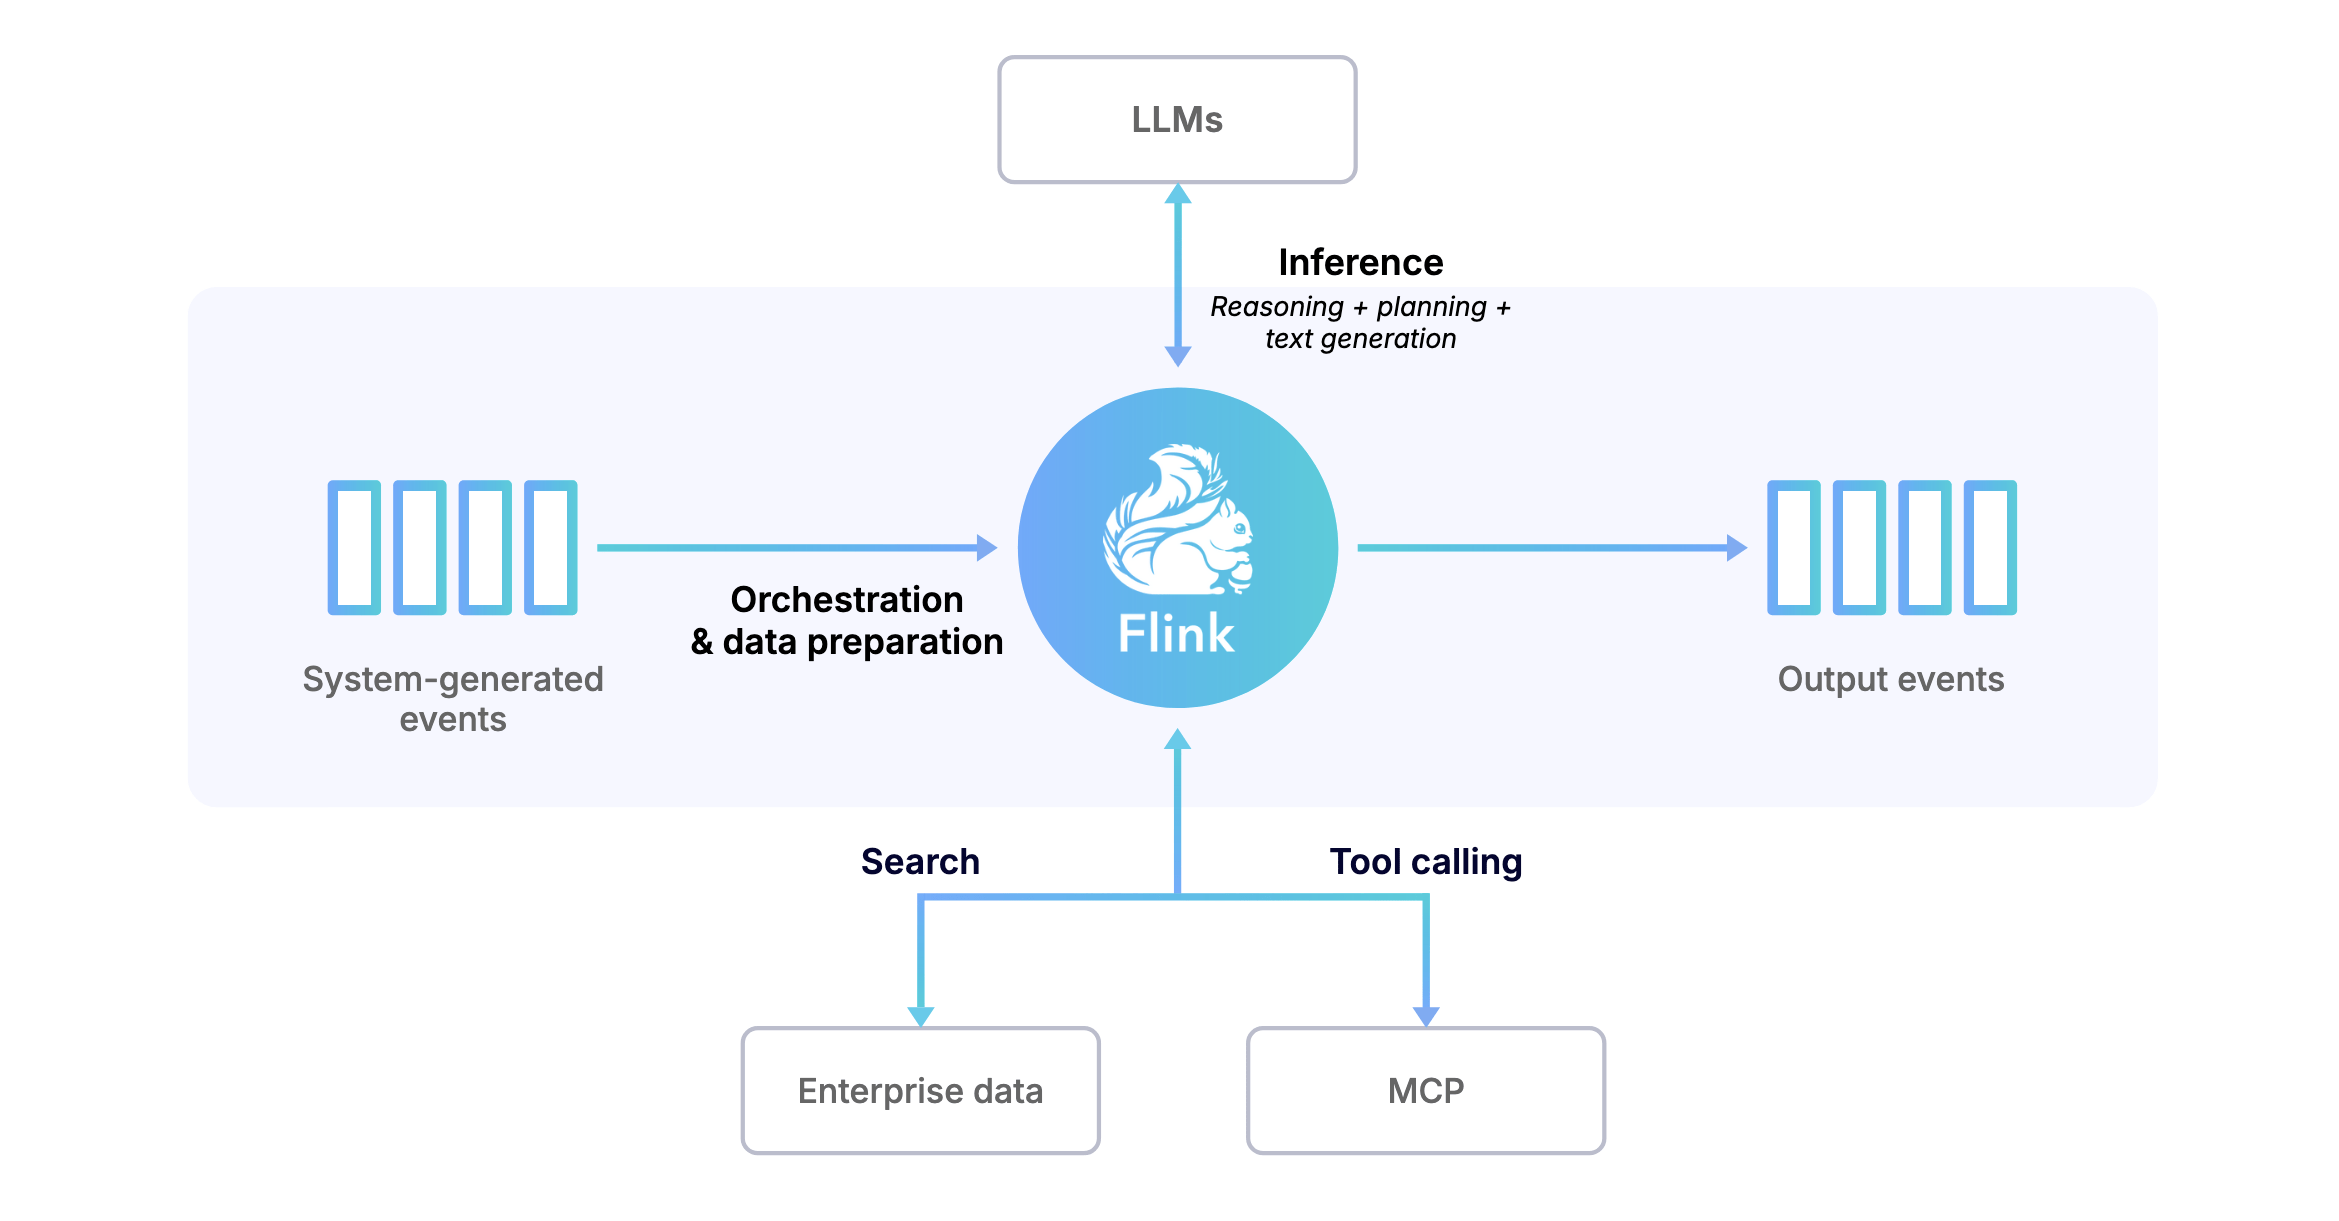
Run always‑on AI agents on your streaming platform.
React to live events with the same guarantees you expect from Flink jobs.
Scale, millisecond latency, and exactly‑once actions.
Reference: https://www.confluent.io/blog/event-driven-flink-agents-enterprise-ai/
Flink Agent
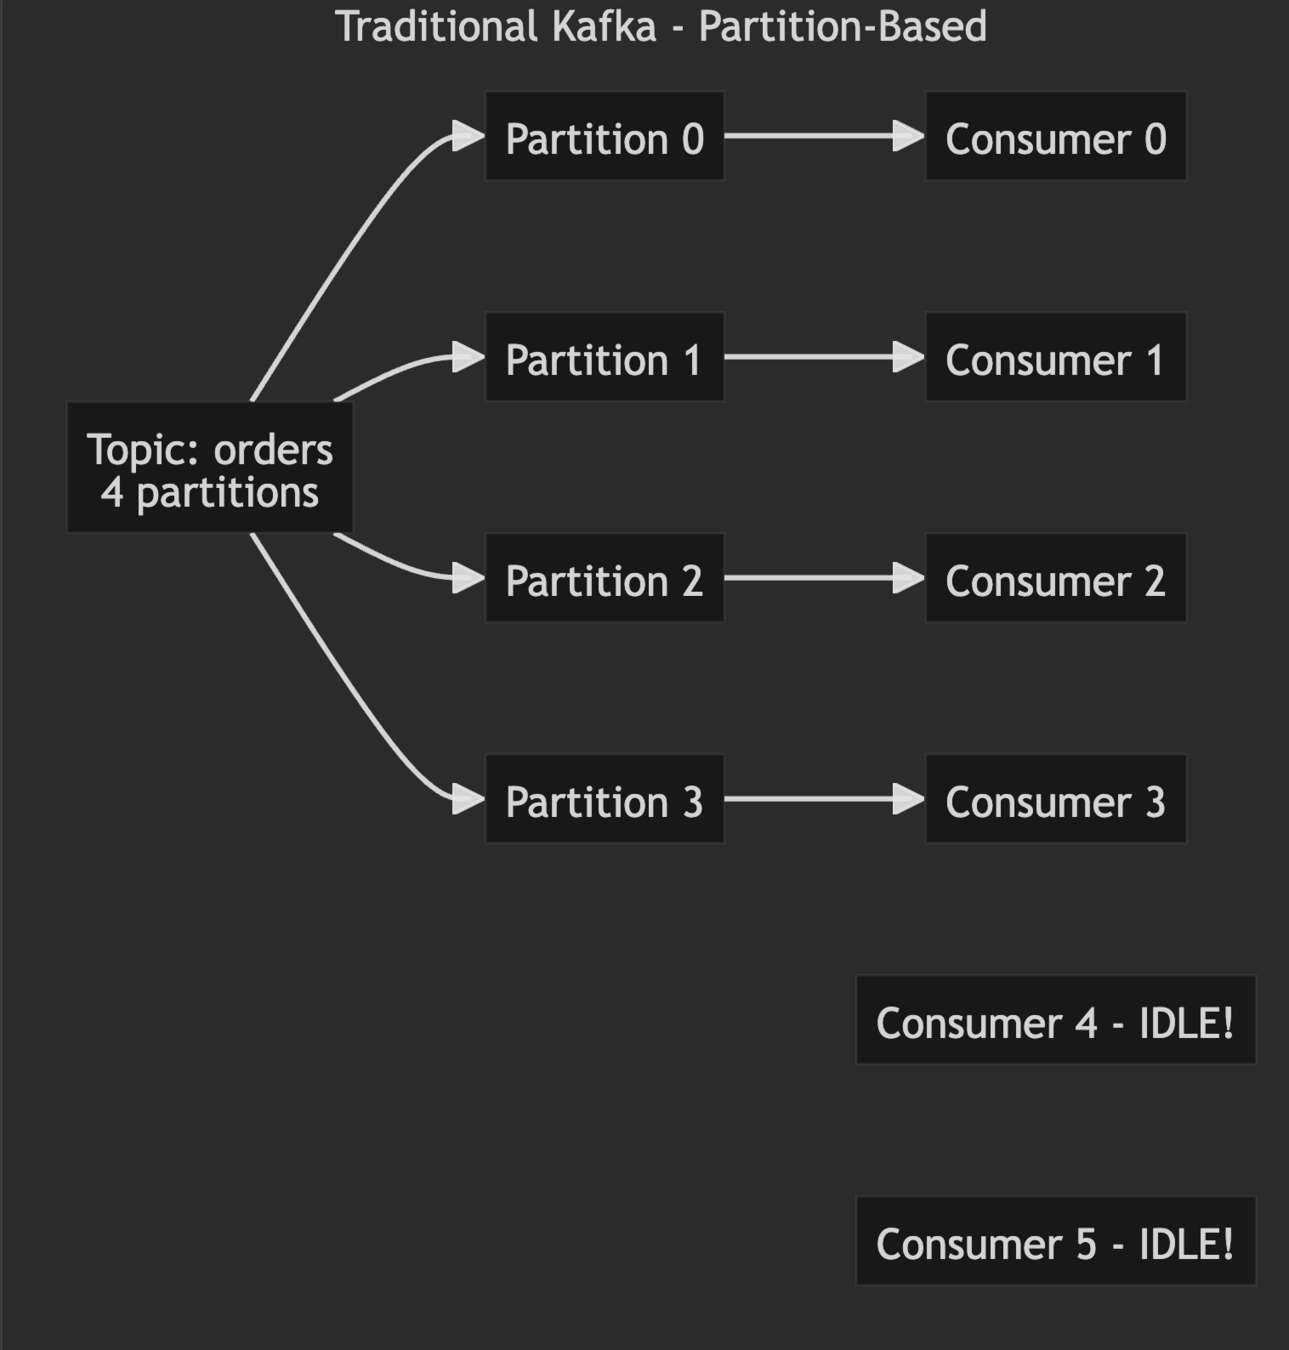
Kafka Queue Semantics
Kafka Queue Semantics
- Higher Throughput
- Low latency and Flexible Scaling
- Less operational overhead at consumer side

Unified realtime AI platform
-
Non-blocking ML Inference
-
Model Lifecycle Management
- Unified Stream+ML
- State Management
- AI building block: Tools, Resources, Memory
- Fault tolerance
The preparation taking place at..


The preparation taking place at..
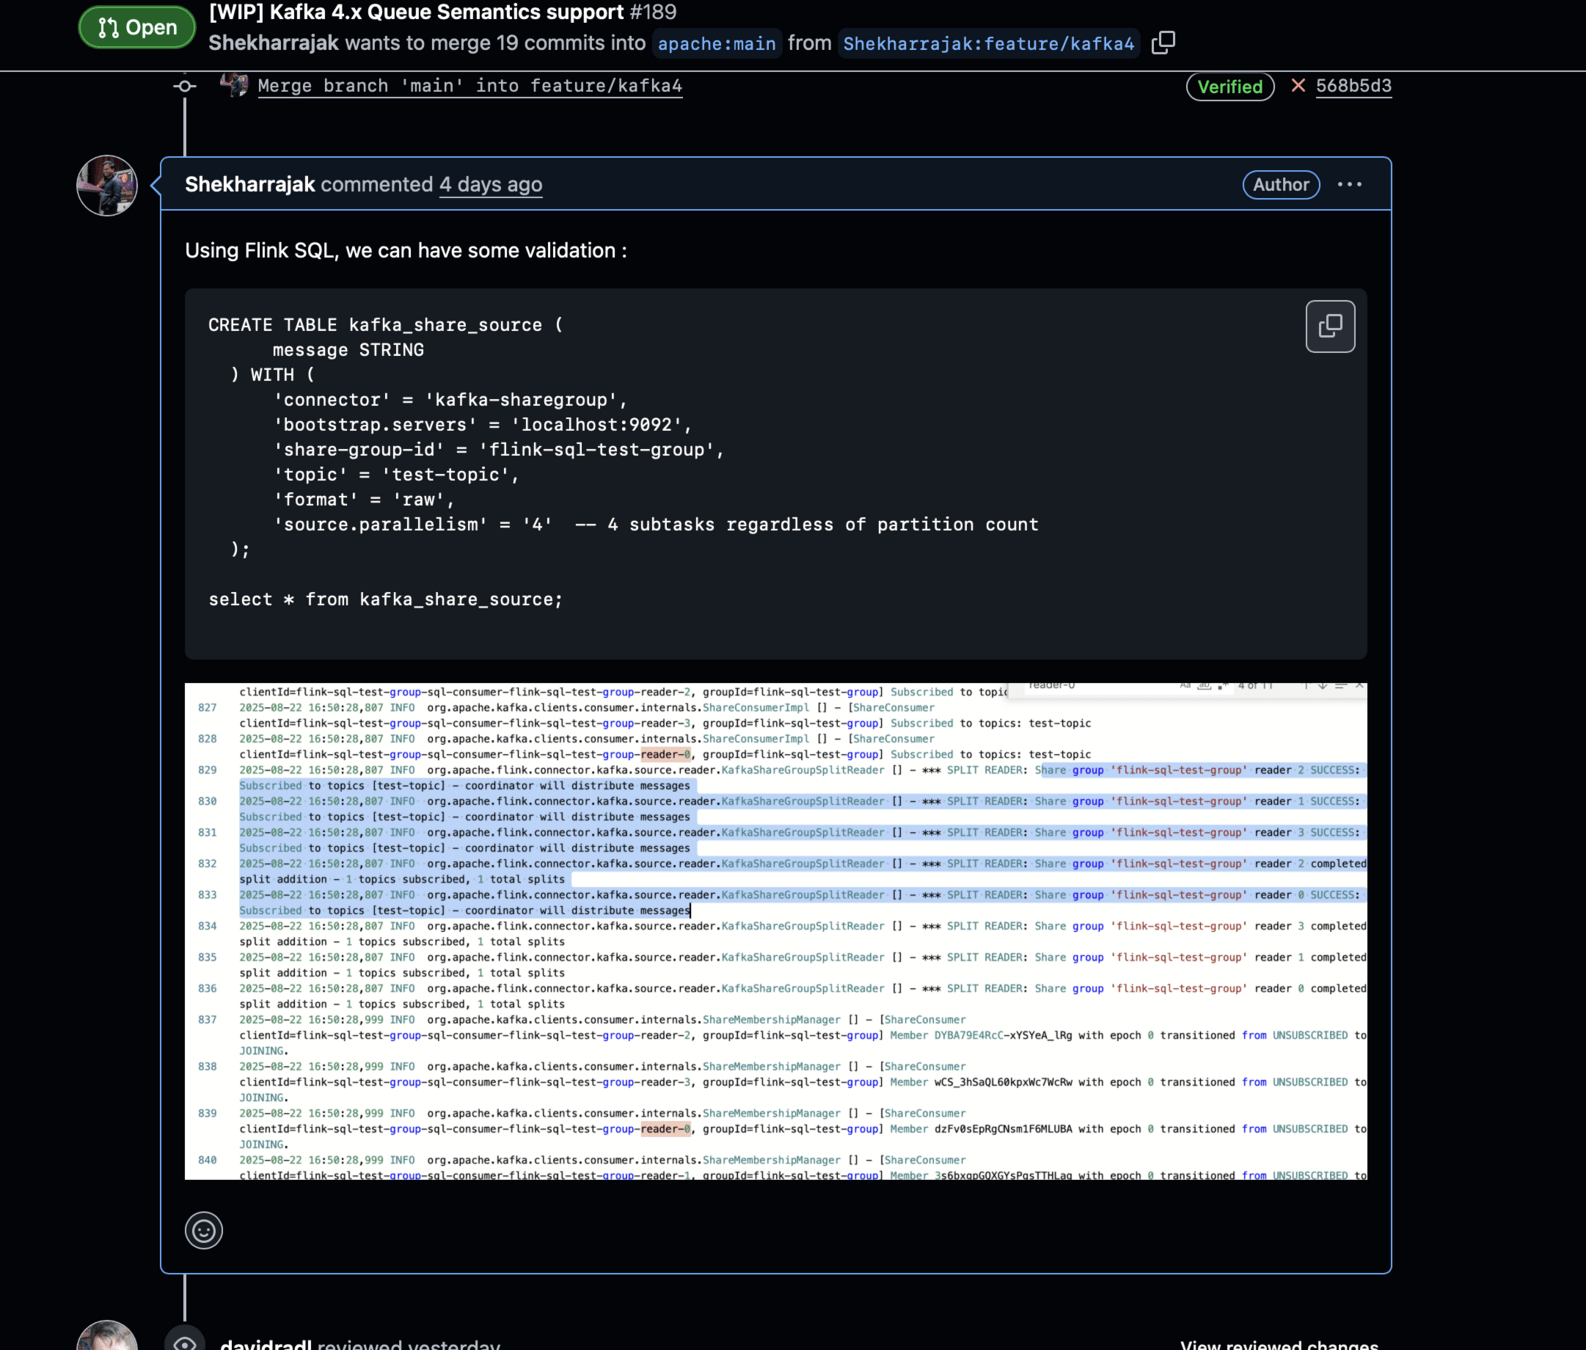
Let's see the system in action
Let's see the system in action
┌─────────────────────────────────────────────────────────────┐
│                     FLINK AGENTS RUNTIME                     │
├─────────────────────────────────────────────────────────────┤
│  ┌─────────┐   ┌─────────────┐   ┌──────────────────────┐  │
│  │ Kafka   │──▶│ Agent Task  │──▶│ LLM Provider         │  │
│  │ Source  │   │             │   │ (OpenAI/Bedrock/etc) │  │
│  └─────────┘   │ • State     │   └──────────────────────┘  │
│                │ • Tools     │                              │
│  ┌─────────┐   │ • Memory    │   ┌──────────────────────┐  │
│  │ Kafka   │◀──│ • Guardrails│──▶│ Tool Registry        │  │
│  │ Sink    │   └─────────────┘   │ (RAG, APIs, DBs)     │  │
│  └─────────┘                     └──────────────────────┘  │
│                                                             │
│  [Checkpointing] [Exactly-Once] [Backpressure] [Scaling]   │
└─────────────────────────────────────────────────────────────┘
Let's see the system in action
[Kafka Events] → [Flink Agent Runtime] → [LLM + Tools + State] → [Actions/Responses]
                         ↓
                  [Exactly-once guarantees]
                  [Checkpoint/Recovery]
                  [Backpressure handling]
Let's see the system in action
# Set up Agents execution environment with Flink env
    agents_env = AgentsExecutionEnvironment.get_execution_environment(env)

    # Add Ollama connection resource
    agents_env.add_resource(
        "ollama_server",
        ResourceDescriptor(clazz=OllamaChatModelConnection, request_timeout=120),
    )
source = KafkaShareGroupSource.builder() \
.set_bootstrap_servers('localhost:9092') \
.set_share_group_id('my-share-group') \
.set_topics('enriched-user-events') \
.set_value_only_deserializer(SimpleStringSchema()) \
.set_starting_offsets(KafkaOffsetsInitializer.earliest()) \
.build()
# Create ReAct Agent for sentiment analysis
    sentiment_agent = ReActAgent(
        chat_model=ResourceDescriptor(
            clazz=OllamaChatModelSetup,
            connection="ollama_server",
            model="qwen3:8b",
        ),
        prompt=sentiment_prompt,
        output_schema=SentimentResult,
    )

    # Apply sentiment agent to the stream
    result_stream = (
        agents_env.from_datastream(
            input=message_stream,
            key_selector=lambda x: x.id
        )
        .apply(sentiment_agent)
        .to_datastream()
    )
Let's see the system in action
Apache Iceberg features for ML use case
Branch,Time Travel & Snapshot
-
Knowledge Base (KB) Versioning and Experimentation
-
main vs experimental
-
- Rollback context or retriever changes instantly
- This issue started after branch merge X
-
Closed-loop learning
-
How did accuracy change after merge X?
-
Thank you!
Linkedin @Shekharrajak
Github @Shekharrajak
Chess.com @Shekharr
YouTube @CodeVigg
Linkedin @JatothBharath
Github @bharathjatoth
YouTube @CodeVigg
Ask not what your country can do for you – ask what you can do for your country